View on GitHub
Open this notebook in GitHub to run it yourself
Quantum Likelihood Estimation (QLE) [1, 2], is a hybrid algorithm for Hamiltonian learning, originally proposed for efficiently learning Hamiltonians from quantum experiments. The basic setting is that the algorithm can access the true Hamiltonian only through the evolution it generates, namely the unitary for an arbitrarily chosen time . Such experiments on the true physical system are considered an expensive resource, analogous to oracle queries, and the goal is to perform as few experiments as possible. QLE has also been demonstrated experimentally [4]. Ref. [3] suggested an optimized approach based on an information-theoretic framework, minimizing the number of oracle calls by jointly optimizing all circuit parameters at each iteration. The QLE problem is defined as follows:
- Input: A set of possible Hamiltonians that may govern the system.
- Promise: One of the Hamiltonians is the true Hamiltonian of the system.
- Output: The The true Hamiltonian.
Keywords: Hamiltonian learning, hybrid quantum-classical algorithms, Bayesian inference.
This notebook implements the Optimal Quantum Likelihood Estimation algorithm, as proposed in Ref. [3], and was developed in collaboration with the paper authors. As a reference, we also implement a naive Quantum Likelihood Estimation.
Defining a Single Qubit Example
Following Ref. [3] we work with a single qubit example, which underlines the idea behind the optimal, information based optimization. We set the quantum model for a single qubit example The QLE circuit consists of three components. The initial state is parameterized by and : (Eq. (8) in Ref. [3]) After Hamiltonian evolution , the measurement basis is rotated by , parameterized by and : (Eq. (9) in Ref. [3])Setting Up a Specific Hamiltonian Set
We define the pool of Hamiltonians and the true index for the demonstration.Output:
Output:
Classical Functions for Maximum Likelihood
The QLE is based on Bayesian inference. We start with a normalized list of weights, each assigned for the different hypothesis : Then, upon measuring outcome from the true system, the likelihood of hypothesis is . The Bayesian weight update from step to reads: where the denominator guarantees that the weights vector stays normalized; See (Eq. (7) in Ref. [3]). Below we define the functionsget_probs_from_qprog, which computes via exact statevector simulation, and bayes_update that performs one step of Eq. (4).
A Standard Quantum Likelihood
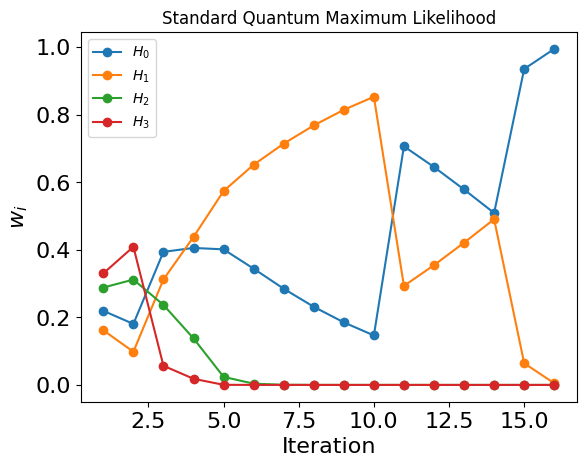
In the naive QLE algorithm, we simply follow a series of Bayesian updates, where the evolution time at each iteration can varies, and the other model parameters are fixed. Here is selected by the Particle Guess Heuristic (PGH): draw two hypotheses from the current weight distribution and set (See Ref. [3])run_qle function, which iterates the standard QLE loop: select via Eq. (5), sample the true Hamiltonian to obtain outcome , and apply the Bayes update (Eq. (4)) until the posterior weight of one hypothesis exceeds the convergence threshold.
Run for the Specific Example
Output:
Output:
Plotting the Convergence History
Output:
An Optimized Quantum Likelihood
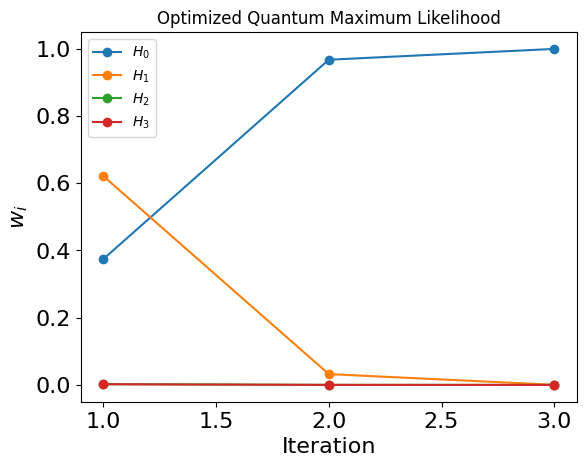
Next, we follow the procedure introduced in Ref. [3]. We find the optimal parameters that maximizes the mutual information, and use simulated annealing for finding them. The optimized QLE selects by minimizing the conditional Shannon entropy over the current posterior : (Eq. (10) in Ref. [3]) Minimizing is equivalent to maximizing the mutual information between the true Hamiltonian and the measurement outcome . Below, we defineconditional_entropy_cost_batch that calculates the cost function for a batch of parameters.
optimize_entropy_sa.
run_optimized_qle function, that runs over the optimized QLE steps.
Compared to the standard QLE (run_qle), we replace the PGH with the simulated annealing optimizer: at each iteration the optimal minimizing is found, the true system is sampled, and the Bayes update (Eq. (4)) is applied.
Run for the Specific Example
Output:
Output:
Plotting the Convergence History
Output: