View on GitHub

Open this notebook in GitHub to run it yourself
Quantum Oracle Sketching is a data-loading algorithm introduced by Zhao et al. [1]. It provides the missing link between classical data access and the coherent oracle queries on which many powerful quantum algorithms are built. The algorithm approximates the desired oracle OfO_f on the fly from a stream of classical samples (xt,f(xt))(x_t, f(x_t)), applying an incremental data-dependent rotation per sample and discarding each sample once consumed. At no point is the dataset stored in either classical or quantum memory. The result is an exponential advantage in space complexity over any classical learner; and when the data distribution varies in time while the learner stays fixed, a super-polynomial advantage in sample complexity is obtained as well: a classical machine requires the number of data examples to scale super-polynomially with the data size NN, while a quantum learner only needs an amount of data that scales linearly, achieving matching accuracy and probabilistic performance. The algorithm treats the following problem:
  • Input: MM classical data samples {(xt,f(xt))}t=1M\{(x_t, f(x_t))\}_{t=1}^{M}, where each xt∈[N]={0,1,…,N−1}x_t \in [N] = \{0,1,\dots,N-1\} is drawn independently from a (possibly time-varying) distribution pp, and ff is the target Boolean function (f[N]→{0,1}f[N]\rightarrow \{0,1\}).
  • Output: A quantum unitary VV on n=⌈log⁡2N⌉n = \lceil\log_2 N\rceil qubits that approximates the corresponding coherent query oracle OO, the phase oracle ∣x⟩→(−1)f(x)∣x⟩|x\rangle \to (-1)^{f(x)}|x\rangle, or a real valued phase ∣x⟩→eiθx∣x⟩|x\rangle \to e^{i \theta_x}|x\rangle to error ϵ\epsilon in diamond distance.
Extensions: Here we consider a Boolean function. Nevertheless, the method can be generalized for multi-bit Boolean output real-valued functions (f:[N]→Rf:[N]\to \mathbb{R}), state preparation (input (j,bj)(j, b_j), encoding the index jj and value bjb_j of a vector element) oracles, and block-encodings of matrices (input is a tuple (i,j,Aij)(i, j, A_{ij}), encoding the elements of a matrix AA). VV can then be used as a drop-in subroutine inside any quantum query algorithm. Complexity
  • Sample complexity: A single ϵ\epsilon-accurate oracle sketch requires M=Θ(N/ϵ)M = \Theta(N/\epsilon) classical samples. To support an arbitrary quantum algorithm that makes QQ queries to total error ϵ\epsilon, each query is sketched to error ϵ/Q\epsilon/Q, giving
Mtotal=Θ ⁣(NQ2/ϵ).M_\text{total} = \Theta\!\bigl(N Q^2 / \epsilon\bigr).
The quadratic dependence on QQ is unavoidable, mirroring the Born-rule relationship between quantum amplitudes and probabilities.
  • Space complexity: O(polylog⁡N)\mathcal{O}(\mathrm{poly}\log N) qubits - the quantum machine never stores the dataset, only its current quantum state.
  • Time complexity: O~(N)\widetilde{\mathcal{O}}(N) in the data-loading stage (one constant-depth controlled gate per sample); subsequent processing of each sample requires only polylog⁡N\mathrm{poly}\log N time. Here the overscript tilde designates possible hidden logarithmic dependencies in NN.
  • Classical lower bound (dynamic case): Any classical machine of size O(N0.99){\cal{O}}(N^{0.99}) that matches the quantum prediction accuracy on a time-varying distribution, requires a super-polynomial number of samples.

Keywords: Quantum Learning Theory, Quantum Machine Learning (QML), Streaming Algorithms

Introduction

Most quantum speedup over a classical baseline is stated relative to an oracle, a unitary OfO_f that encodes the input function ff and acts in superposition. Grover’s search assumes a phase oracle Of∣x⟩=(−1)f(x)∣x⟩O_f|x\rangle = (-1)^{f(x)}|x\rangle; the HHL linear-system solver [5], quantum singular-value transformation (QSVT) [4], and most quantum machine-learning routines rely on a block-encoding oracle for the input matrix; amplitude estimation and quantum walks similarly assume coherent access to the input. This coherent access, the ability to evaluate ff on a superposition of inputs in a single query, is exactly what enables the quadratic and exponential speedups, without it, an in-depth analysis shows that the algorithms collapse to their classical counterparts. Yet real-world classical data, produced one sample at a time by experiments, sensors, or users, does not natively support such queries. The standard remedy is to load the entire dataset into a quantum random-access memory (QRAM [3]), but its fault-tolerance overhead often exceeds the quantum advantage it enables, leaving the most powerful quantum algorithms without a practical interface to massive classical data. Quantum oracle sketching is the algorithm that closes this gap: it constructs an approximate OfO_f on the fly from a stream of classical samples, with no QRAM and no full dataset ever held in memory.

The Streaming-Learning Framework

Quantum oracle sketching is proposed in the context of a specific online-learning model. The framework sets the rules under which both the quantum and the classical baselines operate, and it explains why the comparison between the two is well-posed. Setup.
  • A data-generating process D\mathcal{D} emits a sequence of classical samples z1,z2,…,zMz_1, z_2, \dots, z_M.
Each sample is one observation of the underlying object - a function value zt=(xt,f(xt))z_t = (x_t, f(x_t)) for a Boolean target, a feature-vector / label pair zt=(it,x⃗it,yit)z_t = (i_t, \vec{x}_{i_t}, y_{i_t}) for classification, or an entry zt=(it,jt,Aitjt,kt,bkt)z_t = (i_t, j_t, A_{i_t j_t}, k_t, b_{k_t}) of a linear system Ax⃗=b⃗A\vec{x} = \vec{b}.
  • A learner of size SS (which can be the number of logical qubits composing the quantum learner, or the number of floating-point words for a classical one) observes the samples one at a time.
After seeing ztz_t it updates its memory, then discards ztz_t. At no point is the dataset stored in full. This is known as streaming model.
  • After MM samples, the learner is asked to predict, classify, or compress some property of the underlying process D\mathcal{D} (not of the empirical sample!). Examples: the label of a held-out test feature vector (classification), the value of a quadratic form x⃗⊤Mx⃗\vec{x}^\top \mathcal{M} \vec{x} (linear systems), or the projection of a test point onto the top principal direction (PCA).
The two resources of interest are the machine size SS and the sample count MM. Optimally, we would like to minimize both simultaneously. Static versus dynamic data. The framework allows the data distribution to drift in time, characterized by two parameters:
  • Refreshing time τ\tau: the timescale beyond which samples become effectively uncorrelated.
  • Repetition number RR: the maximum expected number of times any single sample is repeated within a window of τ\tau steps.
When τ→∞\tau \to \infty we recover the static, i.i.d. setting. When τ=O~(N)\tau = \widetilde{\mathcal{O}}(N) the distribution refreshes on the same timescale as the data size, and the quantum advantage in sample complexity becomes super-polynomial. In this regime, any Ω(N0.99)\Omega(N^{0.99})-size classical machine needs super-polynomially many samples while a quantum learner with polylog⁡N\mathrm{poly}\log N qubits suffices with O~(N)\widetilde{\mathcal{O}}(N) samples. End-to-end pipeline. The full quantum learner is a three-stage assembly:
  1. Quantum oracle sketching consumes the stream of classical samples and produces an approximate oracle unitary V≈OfV \approx O_f (the subject of the present notebook).
  2. A quantum query algorithm
  • Grover, QSVT [4], HHL [5], amplitude estimation, etc. - uses VV as a black-box subroutine to prepare a target state ∣ψtarget⟩|\psi_\text{target}\rangle that encodes the desired property of D\mathcal{D}.
  1. Interferometric classical shadows - a sign-preserving variant of the Classical Shadow Tomography protocol [2].
The method extracts a compact classical model from ∣ψtarget⟩|\psi_\text{target}\rangle in polylog⁡N\mathrm{poly}\log N measurements, ready for offline prediction on arbitrary test inputs. This notebook focuses on the first stage of this scheme, covering the variants of the quantum oracle sketching of a Boolean function.

Implementation of the Oracle Sketching Algorithm

Oracle Sketching of a Boolean Function and Uniform Distribution

We aim to implement the Boolean phase oracle O ∣x⟩=(−1)f(x) ∣x⟩,x∈[N], f:[N]→{0,1},O\,|x\rangle = (-1)^{f(x)}\,|x\rangle, \qquad x \in [N],\ f : [N] \to \{0,1\}, given only random classical samples zt=(xt, f(xt))z_t = (x_t,\, f(x_t)) for t=1,…,Mt = 1,\dots,M, where each xtx_t is drawn uniformly from [N]={0,1,…,N−1}[N] = \{0,1,\dots,N-1\}. Per-sample rotation. For each sample we apply a small data-dependent phase rotation that fires only on the basis state ∣xt⟩|x_t\rangle: Vt  =  exp⁡ ⁣(i τ f(xt) ∣xt⟩ ⁣⟨xt∣/M).(1)V_t \;=\; \exp\!\bigl(i\,\tau\, f(x_t)\,|x_t\rangle\!\langle x_t| / M\bigr). \tag{1} Coherent accumulation. Because every VtV_t is diagonal in the computational basis, all factors commute and the product collapses cleanly: V  ≡  ∏t=1MVt  =  exp⁡ ⁣(iτM∑t=1Mf(xt) ∣xt⟩ ⁣⟨xt∣)  =  ∑x=0N−1exp⁡(i τ mx f(x)) ∣x⟩ ⁣⟨x∣,(2)V \;\equiv\; \prod_{t=1}^M V_t \;=\; \exp\!\Bigl(i\tfrac{\tau}{M}\sum_{t=1}^M f(x_t)\,|x_t\rangle\!\langle x_t|\Bigr) \;=\; \sum_{x=0}^{N-1} \exp\bigl(i\,\tau\, m_x\, f(x)\bigr)\,|x\rangle\!\langle x|, \tag{2} where mx=1M∑t1[xt=x]m_x = \frac{1}{M}\sum_t \mathbf{1}[x_t = x] is the empirical frequency of basis label xx. Concentration. As MM grows, mx→p(x)=1/Nm_x \to p(x) = 1/N by the law of large numbers. Picking τ=πN\tau = \pi N makes τ mx→π\tau\, m_x \to \pi and V  ⟶  ∑x=0N−1eiπf(x) ∣x⟩ ⁣⟨x∣  =  ∑x(−1)f(x) ∣x⟩ ⁣⟨x∣  =  O.(3)V \;\longrightarrow\; \sum_{x=0}^{N-1} e^{i\pi f(x)}\,|x\rangle\!\langle x| \;=\; \sum_x (-1)^{f(x)}\,|x\rangle\!\langle x| \;=\; O. \tag{3} Sample complexity. Ref. [1] shows the diamond-distance error decays as ϵ=O(N/M)\epsilon = \mathcal{O}(N/M), so reaching error ϵ\epsilon costs M=Θ(N/ϵ)(4)M = \Theta(N/\epsilon) \tag{4} samples. Each sample is processed once and immediately discarded. Comparison to generic random Hamiltonian simulation. The N/MN/M scaling above is not what a naive random-rotation strategy would deliver. If one instead applied a sequence of small phases exp⁡(i τ hzt/M)\exp(i\,\tau\, h_{z_t}/M) driven by an arbitrary Hamiltonian hzh_z with ∥hz∥=O(1)\|h_z\| = \mathcal{O}(1) - hoping the sequence approximates exp⁡(i τ E[hz])\exp(i\,\tau\,\mathbb{E}[h_z]), randomized-Hamiltonian-simulation results show the operator-norm error compounds to ϵnaive  =  O(N2/M),i.e.Mnaive  =  Θ(N2/ϵ).\epsilon_\text{naive} \;=\; \mathcal{O}(N^2 / M),\qquad \text{i.e.}\qquad M_\text{naive} \;=\; \Theta(N^2 / \epsilon). That extra factor of NN would consume the entire quantum advantage. To support QQ queries with combined error ϵ\epsilon, each individual query must be sketched to error ϵ/Q\epsilon/Q, so per-query naive simulation needs Θ(N2Q/ϵ)\Theta(N^2 Q / \epsilon) samples and the total becomes Mtotalnaive  =  Q⋅Θ(N2Q/ϵ)  =  Θ(N2Q2/ϵ),M_\text{total}^\text{naive} \;=\; Q \cdot \Theta(N^2 Q/\epsilon) \;=\; \Theta(N^2 Q^2/\epsilon), versus the Θ(NQ2/ϵ)\Theta(NQ^2/\epsilon) achieved here - a factor-NN blow-up that would take O~(N)\widetilde{\mathcal{O}}(N)-sample tasks straight back into the regime where any classical machine of size Ω(N0.99)\Omega(N^{0.99}) wins. The improvement to ϵ=O(N/M)\epsilon = \mathcal{O}(N/M) comes from a crucial piece of structure: each VtV_t phases only the one-dimensional subspace ∣xt⟩ ⁣⟨xt∣|x_t\rangle\!\langle x_t|, and distinct values of xx label mutually orthogonal subspaces, so per-sample errors live in disjoint Hilbert-space blocks rather than compounding across the full register. Quantum oracle sketching is, in this sense, a carefully engineered non-generic instance of randomized Hamiltonian simulation, designed precisely to dodge the N2/MN^2/M trap. We begin by importing the required python modules and define the size of the problem NN and the truth table, defining ff.
Output:
We begin by introducing the basic quantum functions, which are utilized to construct the quantum oracle sketching function. The primitive apply_basis_phase realizes exp⁡(iθ ∣xint⟩ ⁣⟨xint∣)\exp(i\theta\,|x_\text{int}\rangle\!\langle x_\text{int}|) by controlling on the equality predicate qvar == x_int; the body phase(theta) becomes a relative phase on the controlled subspace and the identity elsewhere, which is exactly VtV_t. The quantum_oracle_sketch_boolean function iterates over the samples of x_samples, leading to an approximate application of OfO_f.
We pre-filter the classical data so only samples with f(xt)=1f(x_t)=1 enter the circuit (the rest contribute the identity), fix θ=πN/M\theta = \pi N / M, and bake the samples into the circuit at synthesis time. The leading Hadamard transform lets us see the diagonal-phase action of VV on the uniform superposition ∣+⟩⊗n|+\rangle^{\otimes n}.
Output:
Verification on a 2-qubit Bell state via Classiq execution. Take f=[0,0,1,1]f = [0, 0, 1, 1] - a phase on the most-significant-bit subspace. The ideal oracle maps ∣Φ+⟩=(∣00⟩+∣11⟩)/2|\Phi^+\rangle = (|00\rangle + |11\rangle)/\sqrt{2} to ∣Φ−⟩=(∣00⟩−∣11⟩)/2|\Phi^-\rangle = (|00\rangle - |11\rangle)/\sqrt{2}. We prepare ∣Φ+⟩|\Phi^+\rangle on a 2-qubit register, apply the sketched quantum_oracle_sketch_boolean for one random sample sequence of M=500M = 500 samples, then run the inverse Bell preparation (CX followed by H on qubit 0) so that the Bell basis is rotated back to the computational basis: in particular ∣Φ−⟩↦∣10⟩|\Phi^-\rangle \mapsto |10\rangle (i.e. qvar = 1). Measuring the register in the computational basis with sample(...) function makes the fidelity ∣⟨Φ−∣V∣Φ+⟩∣2|\langle\Phi^-|V|\Phi^+\rangle|^2 equal to the probability of observing qvar = 1. The single-realization error scales as N/M\sqrt{N/M}, so the fidelity gap from 11 is of order N/M≈0.008N/M \approx 0.008 on average over realizations, with typical per-shot fluctuations of order N/M≈0.09\sqrt{N/M} \approx 0.09.
Output:
Output:
Output:

Verification of the Sample-Complexity Scaling

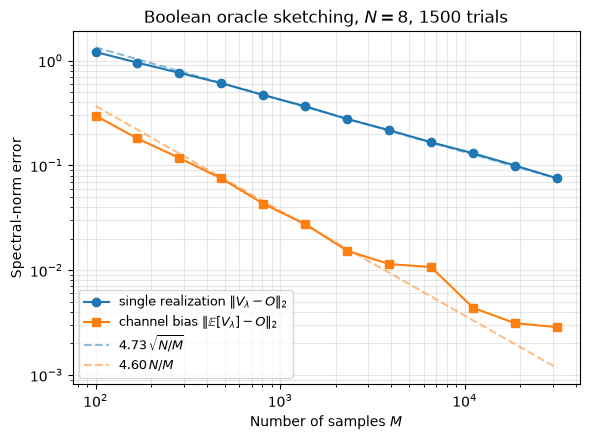
In order to verify the sample complexity, we build the sketched unitary VV classically by collecting MM random samples and assembling the diagonal matrix from eq. (2). Following, we compare the results to the theory and evaluate the scaling constants (hidden by the big-O notation). Two scalings of the error to the ideal oracle OO are worth keeping distinct:
  • Single-realization operator-norm error ∥Vλ−O∥2\|V_\lambda - O\|_2 for one random data sample λ=(x1,…,xM)\lambda = (x_1, \dots, x_M) is dominated by the variance of the empirical frequencies ∣mx−1/N∣=O(1/NM)|m_x - 1/N| = \mathcal{O}(1/\sqrt{NM}).
Each diagonal entry deviates by πN∣mx−1/N∣∼N/M\pi N|m_x - 1/N| \sim \sqrt{N/M}, so the spectral norm scales as ∥Vλ−O∥2=O(N/M)\|V_\lambda - O\|_2 = \mathcal{O}(\sqrt{N/M}).
  • Random-unitary channel C(ρ)=Eλ[Vλ ρ Vλ†]\mathcal{C}(\rho) = \mathbb{E}_\lambda[V_\lambda\, \rho\, V_\lambda^\dagger] - the actual object that gets used inside any quantum query algorithm - has diamond-distance error O(N/M)\mathcal{O}(N/M) to OρO†O \rho O^\dagger.
The improvement over a single realization comes because the random unitary is unbiased to leading order: ∥E[Vλ]−O∥=O(N/M)\|\mathbb{E}[V_\lambda] - O\| = \mathcal{O}(N/M), an order of magnitude better than a single draw. This second scaling drives the M=Θ(N/ϵ)M = \Theta(N/\epsilon) sample complexity. We verify both empirically below by sweeping MM over three decades and, for the channel, averaging VλV_\lambda over independent runs.
Output:
output We obtain a relatively good agreement between theory and numerics, the single realization is obtains an exellect fit to the linear regression, while the channel bias show cases fluctuation due to high error to signal ration. Moreover, the scaling constants are of order one, demonstrating that the quantum sketching algorithm is useful for practical implementations.

Extensions

We now extend the basic sketching algorithm to the case where the data points are sampled from a non-uniform distribution. First, we analyze the case where the probability distribution, p(x)p(x), is known. In practice, this case is scalable only when p(x)p(x) can be defined in terms of O(log⁡(N))O(\log(N)) parameters; otherwise, the memory required to store all the probabilities would ruin the exponential memory advantage. In the second extension we consider an unknown probability distribution, where only the range of probabilities is known. We present an implementation of the two cases and test the latter for a two-qubit operation.

Non-Uniform Known Probability Distribution

The construction above assumed the samples xtx_t are drawn uniformly from [N][N], which let us pick the global scaling τ=πN\tau = \pi N so that τmx→π\tau m_x \to \pi. When the samples are drawn from a known, possibly non-uniform distribution pp on [N][N] with p(x)>0p(x) > 0 everywhere, the same product-and-concentration argument carries through provided we rescale per sample: Vt  =  exp⁡ ⁣(i πp(xt) f(xt) ∣xt⟩ ⁣⟨xt∣/M),V_t \;=\; \exp\!\Bigl(i\,\tfrac{\pi}{p(x_t)}\,f(x_t)\,|x_t\rangle\!\langle x_t|\Big/M\Bigr), so that the empirical-frequency limit mx→p(x)m_x \to p(x) still gives π\pi on each active basis state. The sample complexity becomes M=Θ ⁣(N ∥1/p∥∞/ϵ)M = \Theta\!\bigl(N\,\|1/p\|_\infty / \epsilon\bigr); the worst-case rescaling appears as an effective ∥1/p∥∞\|1/p\|_\infty factor (the maximum value of 1/p(x)1/p(x) for x∈[N]x\in[N]) that reduces to NN for the uniform case. Below we present a generalization of quantum_oracle_sketch_boolean by accepting a per-sample angle thetas[t] = pi / (p(x_samples[t]) * M); the existing apply_basis_phase primitive then realizes each VtV_t. x_samples is assumed pre-filtered to active samples (f(xt)=1f(x_t) = 1). The function reduces to the uniform Boolean qfunc when p=1/Np = 1/N (all angles equal πN/M\pi N / M).

Extension to an Unknown Probability Distribution (via QSVT)

When pp is not known in advance the per-sample angle π/p(xt)\pi / p(x_t) is unavailable. Suppose, however, that we know bounds on the support of pp: pmin⁡≤p(x)≤pmax⁡p_{\min} \le p(x) \le p_{\max} on the support, with condition number κ=pmax⁡/pmin⁡\kappa = p_{\max}/p_{\min}. The construction of Zhao et al. handles this case in three stages. Sketch with the pmax⁡p_{\max}-scaling. Pick t=1/pmax⁡t = 1/p_{\max}. Quantum oracle sketching then approximates U  =  ∑xei p(x)f(x)/pmax⁡ ∣x⟩ ⁣⟨x∣  =  eiΛ,Λ  :=  ∑xp(x)f(x)pmax⁡ ∣x⟩ ⁣⟨x∣.U \;=\; \sum_x e^{i\,p(x) f(x)/p_{\max}}\,|x\rangle\!\langle x| \;=\; e^{i\Lambda}, \qquad \Lambda \;:=\; \sum_x \tfrac{p(x) f(x)}{p_{\max}}\,|x\rangle\!\langle x|. The eigenvalues of Λ\Lambda are 00 on the f=0f = 0 subspace and lie in [ 1/κ, 1 ][\,1/\kappa,\,1\,] on the f=1f = 1 subspace. Expose sin⁡Λ\sin\Lambda with a Hadamard test. Introduce one ancilla qubit aa and the gate S=diag(−i,1)S = \mathrm{diag}(-i, 1). The unitary W  =  Xa Sa Xa Ha (cU†) Xa (cU) Ha  ,W \;=\; X_a\, S_a\, X_a\, H_a\,(cU^{\dagger})\, X_a\,(cU)\, H_a~~, which satisfies ⟨0a∣ W ∣0a⟩  =  U−U†2i  =  sin⁡Λ.\langle 0_a|\,W\,|0_a\rangle \;=\; \frac{U - U^{\dagger}}{2i} \;=\; \sin\Lambda. So the spectrum of the block-encoded operator is 00 on f=0f = 0 and sin⁡(p(x)/pmax⁡)∈[sin⁡(1/κ), sin⁡1]\sin(p(x)/p_{\max}) \in [\sin(1/\kappa),\,\sin 1] on f=1f = 1. Crucially, this is a Hermitian operator with eigenvalues in [−1,1][-1, 1] - the natural domain for a real QSVT polynomial. Apply a threshold polynomial via QSVT. Use the QSVT polynomial of Gilyén-Su-Low-Wiebe, [6] (Polynomial approximation for a threshold function) with threshold λ⋆=sin⁡(1/κ)\lambda^{\star} = \sin(1/\kappa). It is an even real polynomial PP satisfying
  • ∣P(w)∣≤1|P(w)| \le 1 on [−1,1][-1, 1],
  • ∣P(w)−1∣≤ϵ|P(w) - 1| \le \epsilon on [0, λ⋆/2][0,\,\lambda^{\star}/2] (where the f=0f = 0 entries sit),
  • ∣P(w)+1∣≤ϵ|P(w) + 1| \le \epsilon on [λ⋆, 1][\lambda^{\star},\,1] (where the f=1f = 1 entries sit),
  • degree d=O(log⁡(1/ϵ)/λ⋆)d = O(\log(1/\epsilon)/\lambda^{\star}).
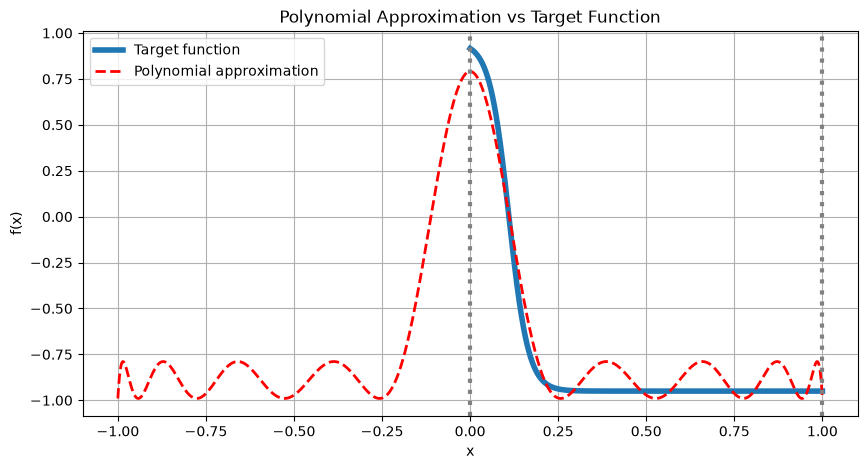
We choose a hyperbolic tangent function (with absolute value of the variable) as an approximate to the ideal (non-smooth) threshold function: f(w)=stanh⁡(a∣w∣−bλ⋆/λ⋆)  ,f(w) = s \tanh(a |w| - b \lambda^{\star} / \lambda^{\star})~~, where a=4a = 4 and b=0.5b=0.5 are chosen so to minimize rapid changes (reducing the required polynomial order), while when f(w>λ⋆)≈−sf(w>\lambda^{\star})\approx -s, s=0.95s=0.95 is the scale constant to keep PP safely within the valid range [−1,1][-1, 1]. This target function constitutes a smooth target function for the QSVT polynomial, enabling an efficient and exact approximation. Applied to WW via QSVT, the block ⟨0a∣PQSVT(W,ϕ)∣0a⟩\langle 0_a | P_{\text{QSVT}}(W, \phi) | 0_a \rangle equals P(sin⁡Λ)P(\sin\Lambda), which is ϵ\epsilon-close to the target oracle O=∑x(−1)f(x)∣x⟩ ⁣⟨x∣O = \sum_x (-1)^{f(x)} |x\rangle\!\langle x|. The QSVT degree scales as Q  =  O ⁣(log⁡(1/ϵ)sin⁡(1/κ))  ≤  O ⁣(κ log⁡(1/ϵ))  ,Q \;=\; O\!\left(\frac{\log(1/\epsilon)}{\sin(1/\kappa)}\right) \;\le\; O\!\bigl(\kappa\,\log(1/\epsilon)\bigr)~~, while the total sample complexity in the IID case is M  =  O ⁣(pmax⁡pmin⁡2⋅log⁡2(1/ϵ)ϵ)  .M \;=\; O\!\left(\frac{p_{\max}}{p_{\min}^2}\cdot\frac{\log^2(1/\epsilon)}{\epsilon}\right)~~. Crucially, no classical knowledge of pp itself enters: only the bounds pmin⁡,pmax⁡p_{\min}, p_{\max} are used, and only to fix t=1/pmax⁡t = 1/p_{\max} and the QSVT degree. We first set up the problem and introduce the utility functions hadamard_test_W, which performs a block encoding of sin⁡(Λ)\sin(\Lambda), and proj_W_block, which is used as both projectors of the QSVT algorithm.
output
Output:
Output:
In the plot above, we compare the even target function to the QSVT polynomial approximation. For better agreement, one can increase the polynomial order, at the expense of an increase in the circuit depth.

Verification on a 2-Qubit Bell State via Classiq Execution

With f=[0,0,1,1]f = [0, 0, 1, 1] the ideal oracle is O=I⊗ZO = I \otimes Z, the same phase on the most-significant-bit subspace used in the Boolean cell above, so OO again maps ∣Φ+⟩=(∣00⟩+∣11⟩)/2|\Phi^+\rangle = (|00\rangle + |11\rangle)/\sqrt{2} to ∣Φ−⟩=(∣00⟩−∣11⟩)/2|\Phi^-\rangle = (|00\rangle - |11\rangle)/\sqrt{2}. The unknown-pp pipeline replaces the direct sketched oracle by the QSVT polynomial P(sin⁡Λ)P(\sin\Lambda) block-encoded in WW, which approximates OO inside the ∣0⟩aux_W|0\rangle_{\text{aux\_W}} ancilla subspace. We prepare ∣Φ+⟩|\Phi^+\rangle, apply the full QSVT chain, and then run the inverse Bell preparation so that ∣Φ−⟩↦∣10⟩|\Phi^-\rangle \mapsto |10\rangle (qvar = 1). Post-selecting on the QSVT block (aux_W = qsvt_aux = 0) and measuring qvar gives the in-block fidelity ∣⟨Φ−∣ PQSVT(W) ∣Φ+⟩∣2|\langle\Phi^-|\,P_{\text{QSVT}}(W)\,|\Phi^+\rangle|^2.
Output:
Output:
Output:
Output:
We obtain good fidelity (≈0.98\approx 0.98), with high probability (pblock≈0.8p_{\text{block}}\approx 0.8). This verifies the accuracy of the oracle sketching algorithm. Note however, that the accuracy comes with an associated cost, as an accurate approximation of the threshold function requires a high QSVT order, which in turn, leads to a deep circuit (circuit depth: ∼8500\text{circuit depth: }\sim 8500).

Summary

Quantum oracle sketching converts a stream of classical samples (xt,f(xt))(x_t, f(x_t)) into an approximate coherent oracle V≈OfV \approx O_f in Θ(N/ϵ)\Theta(N/\epsilon) samples. We analyzed the sample complexity scaling of the Boolean / uniform case, verifying that the scaling constants are relatively small. Following, we demonstrate the performance of the oracle sketching by analyzing the accuracy of a two-qubit state transformation. Finally, we presented extensions to non-uniform known and unknown probability distributions.

References

[1] Zhao, H., Zlokapa, A., Neven, H., Babbush, R., Preskill, J., McClean, J. R., and Huang, H.-Y. Exponential quantum advantage in processing massive classical data. arXiv:2604.07639 (2026) [2] Huang, H.-Y., Kueng, R., and Preskill, J. Predicting many properties of a quantum system from very few measurements. Nature Physics 16, 1050-1057 (2020). https://doi.org/10.1038/s41567-020-0932-7. arXiv [3] Giovannetti, V., Lloyd, S., and Maccone, L. Quantum random access memory. Physical Review Letters 100, 160501 (2008). https://doi.org/10.1103/PhysRevLett.100.160501. arXiv [4] Gilyén, A., Su, Y., Low, G. H., and Wiebe, N. Quantum singular value transformation and beyond: exponential improvements for quantum matrix arithmetics. In Proceedings of the 51st Annual ACM SIGACT Symposium on Theory of Computing, 193-204 (2019). https://doi.org/10.1145/3313276.3316366. arXiv. [5] Harrow, A. W., Hassidim, A., and Lloyd, S. Quantum algorithm for linear systems of equations. Physical Review Letters 103, 150502 (2009). https://doi.org/10.1103/PhysRevLett.103.150502. arXiv. [6] Martyn, J. M., Rossi, Z. M., Tan, A. K., and Chuang, I. L. Grand unification of quantum algorithms. PRX Quantum 2, 040203 (2021). https://doi.org/10.1103/PRXQuantum.2.040203. arXiv.